ARTIFICIAL INTELLIGENCE
FP8 Training and the Numerical Margin That Keeps Learning Stable
September 2026 results expose subtle failure modes in eight-bit attention and reinforcement learning, showing why faster arithmetic still needs careful invariants.
Research checked
Newest cited publication
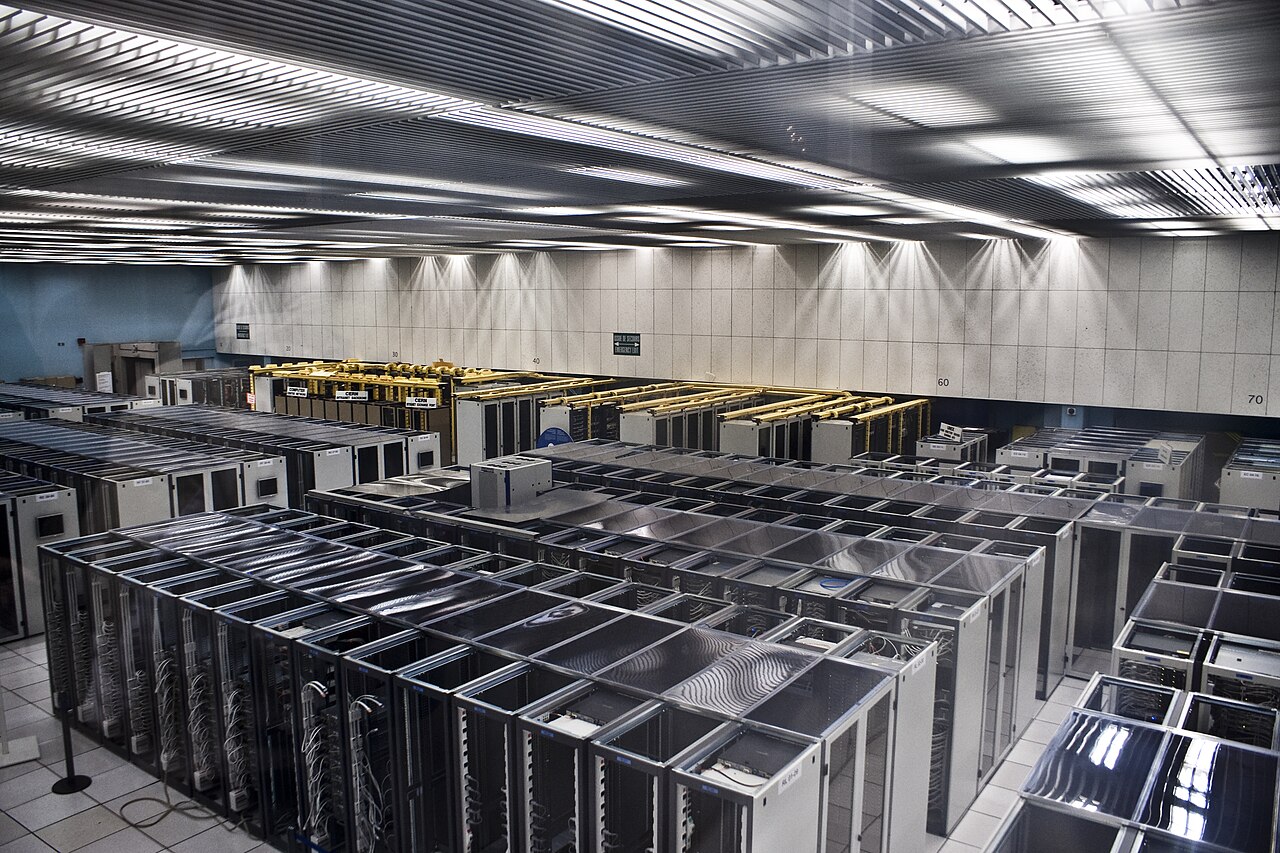
CERN’s server room in 2009 provides infrastructure context for numerical efficiency; the FP8 experiments and their hardware are identified separately in the text.
Florian Hirzinger — www.fh-ap.com · Image source · CC BY-SA 3.0

A training run can perform billions of fast numerical operations and still learn the wrong thing because a small inconsistency keeps recurring. That is the central tension in eight-bit floating-point training. FP8 offers compact numbers and high arithmetic throughput on suitable hardware, but learning depends on more than a visually similar forward answer. Gradients, accumulated updates, and comparisons between policies must remain meaningful over many steps. September 2026 preprints on attention and reinforcement learning make this issue unusually concrete. They identify failures that short runs or smaller models can conceal and propose targeted corrections. The direction is encouraging, but the lesson is specific: low precision becomes reliable by protecting the mathematical relationships the optimization procedure needs, not by declaring that eight bits are always enough.
Eight bits need a scale and a boundary
Floating-point formats divide a limited bit budget between sign, exponent, and fraction. The exponent provides range; the fraction controls spacing between nearby values. In practical low-precision training, scaling and mixed-precision choices determine which tensors use the compact format and which retain more numerical room. DeepSeek-V3’s February 2025 report revision describes an FP8-centered mixed-precision framework at large scale, including fine-grained quantization and higher-precision accumulation. It does not claim that every operation is performed or stored in eight bits.
A deliberately crude rounding example explains why scale matters. Suppose a toy representation stores values only at multiples of 0.1. An update from 1.0 to 1.03 rounds back to 1.0, so the change disappears. If many such updates should accumulate, discarding each one separately produces a different trajectory from accumulating them in a finer representation and rounding later. Real FP8 has nonuniform spacing, but the underlying issue remains: the location of rounding in a computation can matter as much as the nominal format.
Fast matrix multiplication leaves other state behind
COAT, accepted at ICLR 2025 after an October 2024 preprint and February 2025 revision, targets optimizer states and activations that can remain expensive even when linear-layer arithmetic uses FP8. It combines distribution-aware treatment of optimizer state with mixed-granularity activation quantization. Its reported end-to-end memory and speed improvements are measurements for the tested models and hardware. The important conceptual contribution is widening the accounting beyond the multiplication kernel.
Consider an invented training setup whose memory is split into 20 units of weights, 40 of optimizer state, 30 of activations, and ten of temporary storage. Halving the weight allocation alone reduces total memory from 100 to 90 units. Halving weights, optimizer state, and activations would reduce it to 55, if all three changes were numerically acceptable. This arithmetic is not a COAT benchmark. It explains why an apparently dramatic change in one format can produce a modest system-level saving, and why more ambitious compression must confront the different statistical roles of each stored quantity.
September 2026 puts an invariant under the microscope
Delta-Matching, submitted on September 29, 2026, studies inconsistencies between forward and backward attention computations under quantization. The authors describe a stale-delta error and report that a modest gap at 569 million parameters became more damaging in their larger 1.67-billion- and 5.29-billion-parameter tests. Their correction restores a zero-row-sum property of the softmax gradient under stated numerical assumptions. They report matching mixed-precision baselines in the tested settings; the preprint is not a guarantee for every architecture or indefinitely long run.
The invariant has an intuitive basis. Adding the same constant to every input score of a softmax leaves its output probabilities unchanged. A consistent gradient therefore should not request learning along that all-equal direction: the score-gradient entries sum to zero. Rounding can make separately computed pieces disagree and introduce a small spurious component. My interpretation is that preserving such an identity is a stronger debugging target than merely checking whether individual tensor errors look small. It connects a numerical symptom to a direction that the underlying mathematics says should be irrelevant.
A gradient is more than its component magnitudes
GeoFP8, first submitted in July 2026 and revised on September 30, studies compressed gradient communication across devices. The work transforms gradients into geometry-aware coordinates before quantization, seeking to reduce direction-dependent distortion. Its experiments use Llama models at 300 million and 600 million parameters; the reported 7.6 percent end-to-end time reduction is for the latter on 64 GH200 devices. That scope matters: a distributed communication result at these scales does not demonstrate the same gain for every frontier training workload.
For intuition, imagine a two-component gradient of 100 and 0.1 whose smaller component is nevertheless important to a sensitive parameter. A single coarse scale can preserve the large component while effectively erasing the small one. Changing coordinates or local scaling can redistribute the representational budget, though the transformation itself has a cost. The experiment must therefore compare final quality and total elapsed time against the same optimizer and communication path. Merely proving that the encoded vector has fewer bytes would leave both the optimization and systems questions unanswered.
Rounding can change which mistakes receive a penalty
A September 19, 2026 preprint on full-pipeline FP8 reinforcement learning reports entropy surges and degraded outputs despite prior efforts to correct training–inference mismatches. The authors trace a mechanism to distorted importance ratios: some tokens with negative advantage are pushed outside a clipping region and receive inappropriate gradient treatment. Their calibrated-clipping method matches bounds to higher-precision distributions, with experiments covering eight- to 32-billion-parameter models under the tested algorithms. This is a targeted empirical result, not a general proof that clipping fixes all low-precision reinforcement learning.
A toy decision boundary makes the risk visible. Suppose a simplified update rule treats a ratio below 0.80 differently from one above it. Values of 0.799 and 0.801 are numerically close but lie on opposite sides. A rounding error of 0.003 can change the branch taken. This example is not the paper’s complete objective; it explains why average numerical error can miss changes in discrete training behavior. Algorithms with thresholds need diagnostics for threshold crossings, particularly when those crossings repeatedly suppress the correction of bad outputs.
A long run is a different experiment
The cited studies concern different parts of training: multiplication, memory state, attention gradients, inter-device communication, and policy updates. Their corrections should not be assembled into an assumed universal recipe without compatibility tests. My proposed validation sequence would first check numerical invariants in small controlled examples, then compare learning curves at increasing duration and scale, and finally inspect downstream behavior. Loss, throughput, peak memory, and restart frequency should be reported together, including the overhead of monitoring and any high-precision fallback.
A final endpoint score can hide a narrow numerical margin. Two runs may end equally well while one survives only because its data order never produces extreme activations. Testing multiple seeds and difficult distributions helps distinguish a robust method from a fortunate trajectory. The 2026 progress is valuable precisely because it names mechanisms that can be measured and corrected. Faster low-precision training is most convincing when it preserves the relationships that make learning coherent, and when the evidence remains explicit about the scales, durations, and numerical assumptions actually tested.
Recovery behavior also belongs in the experiment. If an error monitor triggers, researchers should record whether the run changes precision, repeats a step, or reloads a checkpoint, and include that extra work in the timing. This is a proposed reporting practice rather than a feature established by every cited method. A transparent recovery log makes the difference between a numerically resilient system and an apparently smooth curve produced by unreported interventions.
Sources & further reading
Primary papers, project documentation, and research releases used in this article. Publication dates below refer to the sources themselves.
- DeepSeek-V3 Technical ReportarXivPublished Checked
- COAT: Compressing Optimizer states and Activation for Memory-Efficient FP8 TrainingarXivPublished Checked
- Delta-Matching: Closing the Final Gap of Native 8-bit Training for LLMsarXivPublished Checked
- GeoFP8: Geometry-Aware FP8 Gradient Compression for Distributed LLM TrainingarXivPublished Checked
- Towards Full Pipeline FP8 Reinforcement Learning for LLMsarXivPublished Checked
FOLLOW THE QUESTION
Study engineering foundations